
Failure Modes
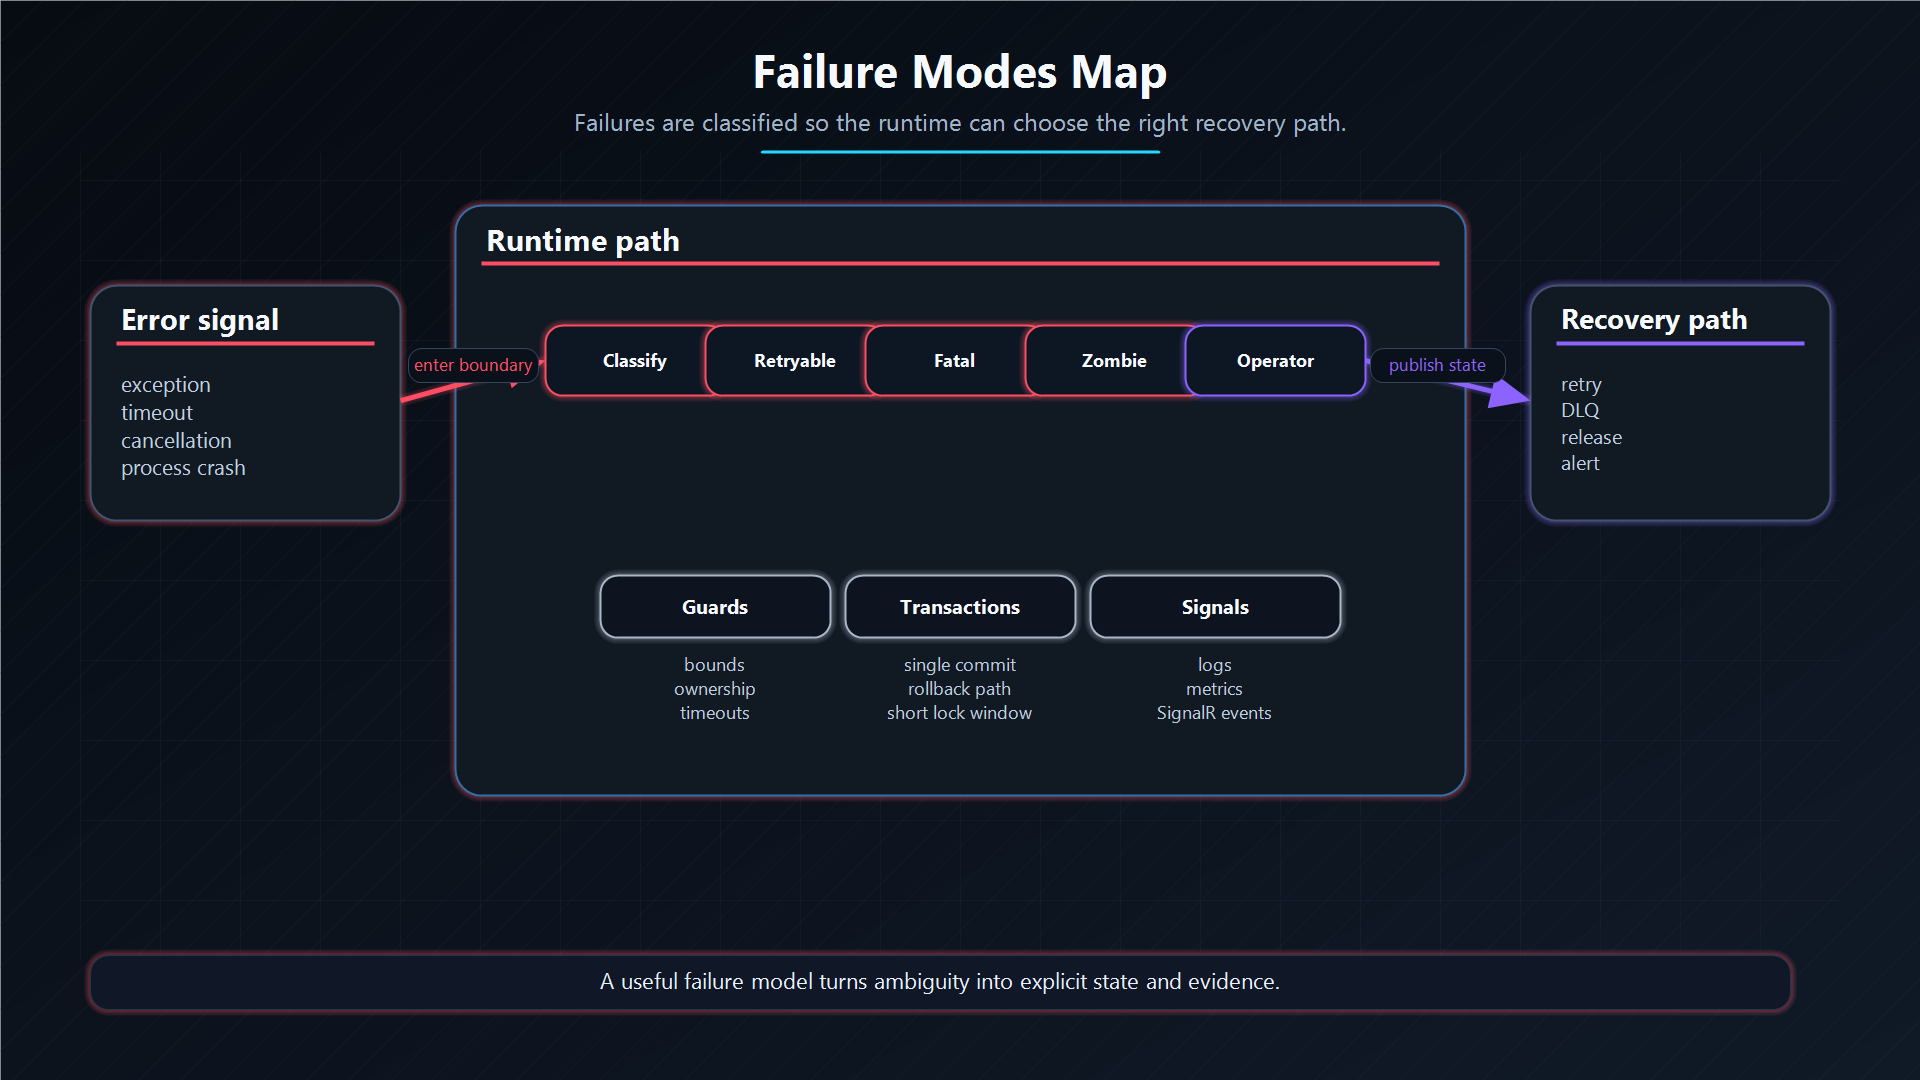
Эта страница группирует failures, которые ChokaQ рассчитан пережить или явно показать.
Failure table
| Failure | ChokaQ behavior | Remaining responsibility |
|---|---|---|
| Host crashes before fetch | Job остается pending в JobsHot. | Monitor queue lag. |
| Host crashes after fetch before processing | Fetched recovery возвращает row в pending. | Tune fetched timeout. |
| Host crashes during processing | Heartbeat expires; zombie rescue moves row to DLQ. | Inspect side effects before resurrection. |
| Handler throws transient error | Job retries with delay, если budget remains. | Classify exceptions accurately. |
| Handler throws fatal error | Job fast-fails в DLQ. | Fix code/payload. |
| SQL deadlock or transient outage | SQL retry policy retries storage operation. | Monitor SQL health. |
| SQL schema missing | Health check fails; workers cannot run correctly. | Run migrations/bootstrap. |
| SignalR disconnects | Dashboard can refresh from storage. | Do not treat SignalR as source of truth. |
| Operator bulk purges wrong rows | Data is gone. | Require authorization, preview, typed confirmation. |
Worst case to understand
Самый сложный случай:
- handler выполняет external side effect;
- process crashes before Archive;
- recovery позже снова делает job executable.
ChokaQ не может знать, произошел ли external side effect. Handler должен использовать business idempotency key или downstream provider idempotency.
Архитектурное решение
ChokaQ разделяет failures на две категории: failures, которые runtime может safely repair automatically, и failures, которые должны быть surfaced для human или application-level judgment. Это различие объясняет, почему Fetched rows можно возвращать в Pending, а Processing zombies перемещаются в DLQ.
Альтернатива - максимизировать automatic retry. В load tests это может выглядеть привлекательно, но скрывает трудную distributed-systems проблему: crashed handler мог уже вызвать external system. ChokaQ выбирает explicit visibility вместо притворства, что queue может гарантировать exactly-once side effects across arbitrary dependencies.
Trade-off - operational work. Teams должны monitor DLQ, писать idempotent handlers и определять resurrection policy для business-critical jobs.
Дополнительные вопросы
Какие failures автоматически safe to retry?
Fetched-but-not-started jobs и явно transient handler failures внутри retry budget.
Какие failures требуют operator judgment?
Processing zombies, malformed payloads, exhausted retries и destructive operator actions.
Какая главная нерешенная distributed systems problem?
Exactly-once external side effects across arbitrary systems.