
SQL Schema Atlas
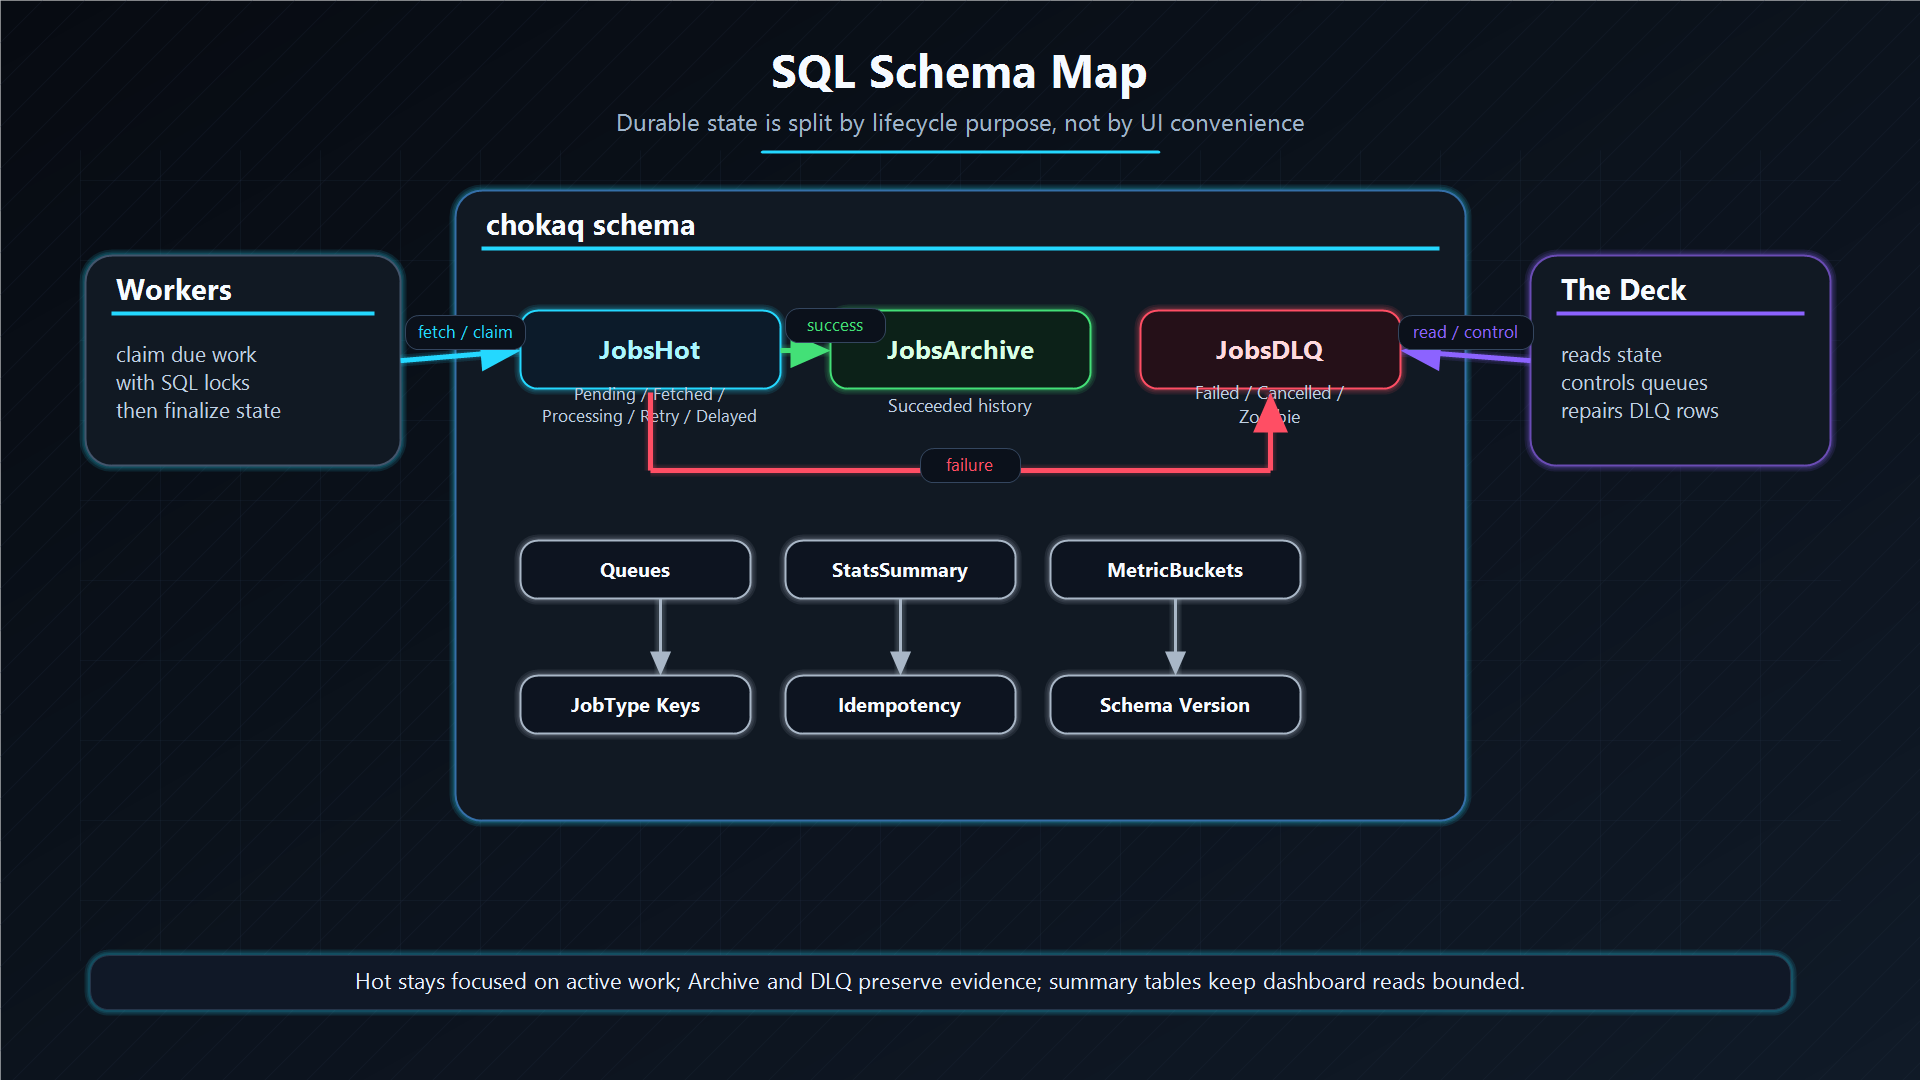
SQL Server storage в ChokaQ построен вокруг active work, immutable history, operator recovery, lifetime counters, rolling metrics, queue configuration и schema migration metadata.
Default schema name - chokaq.
Tables
| Table | Purpose | Hot path? |
|---|---|---|
JobsHot | Active work: pending, fetched, processing, delayed retry. | Yes |
JobsArchive | Успешно завершенные jobs. | No |
JobsDLQ | Failed, cancelled, zombie или operator-held jobs. | No |
StatsSummary | Lifetime counters per queue. | No |
MetricBuckets | Recent throughput и failure-rate aggregates. | No |
Queues | Runtime configuration очередей. | Yes, read by workers |
SchemaMigrations | Applied ChokaQ SQL schema versions. | Startup/ops |
JobsHot
JobsHot - единственная таблица, которую воркеры сканируют для поиска executable work. Держать ее маленькой - главное performance decision в модели Three Pillars.
Ключевые колонки:
| Column | Meaning |
|---|---|
Id | Stable job identifier. |
Queue | Queue partition и operational control boundary. |
Type | Persisted job type key. |
Payload | Serialized job payload. |
Tags | Optional operator/search metadata. |
IdempotencyKey | Optional active-work dedupe key. |
Priority | Чем выше значение, тем раньше fetch. |
Status | Pending, fetched или processing. |
AttemptCount | Число executions, дошедших до Processing. |
ScheduledAtUtc | Future eligibility time для delays и retries. |
WorkerId | Текущий worker owner после fetch. |
HeartbeatUtc | Processing liveness signal. |
Важные indexes:
| Index | Supports |
|---|---|
IX_JobsHot_Fetch | Worker fetch ordering by queue, priority, schedule, creation time. |
IX_JobsHot_Idempotency | Unique active idempotency key. |
IX_JobsHot_QueueStats | Queue dashboard counts. |
IX_JobsHot_PendingLag | Queue lag health checks. |
IX_JobsHot_StatusCreated | Active job dashboard view. |
IX_JobsHot_FetchedRecovery | Abandoned fetched-job recovery. |
IX_JobsHot_ProcessingHeartbeat | Zombie detection. |
JobsArchive
JobsArchive хранит succeeded jobs после успешного final transition. Она не участвует в worker fetch path.
Indexes поддерживают recent history, queue-specific history и tag search. Archive может расти независимо от active work, потому что воркеры не сканируют его для новых jobs.
JobsDLQ
JobsDLQ хранит failed, cancelled, zombie и operator-held jobs. Она питает inspection, edit, resurrection, bulk requeue, bulk purge и failure grouping.
Важные indexes:
| Index | Supports |
|---|---|
IX_JobsDLQ_Date | Recent DLQ view. |
IX_JobsDLQ_Queue | Queue-scoped DLQ inspection. |
IX_JobsDLQ_Reason | Failure taxonomy filtering. |
IX_JobsDLQ_Type | Type-key failure triage. |
IX_JobsDLQ_CreatedAt | Age-based cleanup and investigation. |
StatsSummary
StatsSummary хранит lifetime counters per queue:
- succeeded total;
- failed total;
- retried total;
- last activity timestamp.
Это избавляет от пересчета lifetime counters через сканирование Archive и DLQ.
MetricBuckets
MetricBuckets хранит recent completion aggregates. ChokaQ обновляет buckets внутри той же transaction, которая перемещает job в Archive или DLQ.
Так dashboard throughput остается дешевым и стабильным:
- Archive отвечает на investigation questions;
- DLQ отвечает на recovery questions;
MetricBucketsотвечает на recent-rate questions.
Queues
Queues - runtime control table. Она хранит:
- queue name;
- paused/active flags;
- per-queue zombie timeout;
- optional max worker budget;
- last update timestamp.
Workers читают эту таблицу, чтобы не fetch'ить paused queues и enforcing'ить per-queue capacity.
SchemaMigrations
SchemaMigrations записывает applied ChokaQ schema versions. Она превращает first-start bootstrap в auditable operation, а не полагается только на idempotent CREATE TABLE IF MISSING logic.
Архитектурное решение
Почему этот pattern?
Schema разделяет active work и historical evidence. Это держит worker queries маленькими, но сохраняет completed и failed jobs для operators.
Trade-offs
Переходы между таблицами требуют transaction integrity. Implementation должен аккуратно избегать copy-then-delete bugs. ChokaQ использует короткие SQL transactions и OUTPUT, чтобы сделать moves atomic.
Рассмотренные альтернативы
| Alternative | Benefit | Cost |
|---|---|---|
Single Jobs table with status column | Простая model. | Hot path деградирует по мере роста history. |
| Broker-only queue | High throughput. | Менее прозрачное operational state без дополнительного storage. |
| Archive outside SQL | Меньше database. | Сложнее debugging и split-brain evidence. |
Дополнительные вопросы
Почему не хранить каждое job в одной таблице?
Потому что active fetch queries делили бы indexes и storage с годами history, делая worker path чувствительным к retention.
Почему materialize MetricBuckets?
Потому что dashboard rate windows не должны сканировать mutable history tables или меняться, когда operator purges/requeues DLQ rows.
Главный риск этой schema?
Cross-table moves должны быть atomic. Поэтому final transitions используют database transactions и deleted-row capture.