
Telemetry
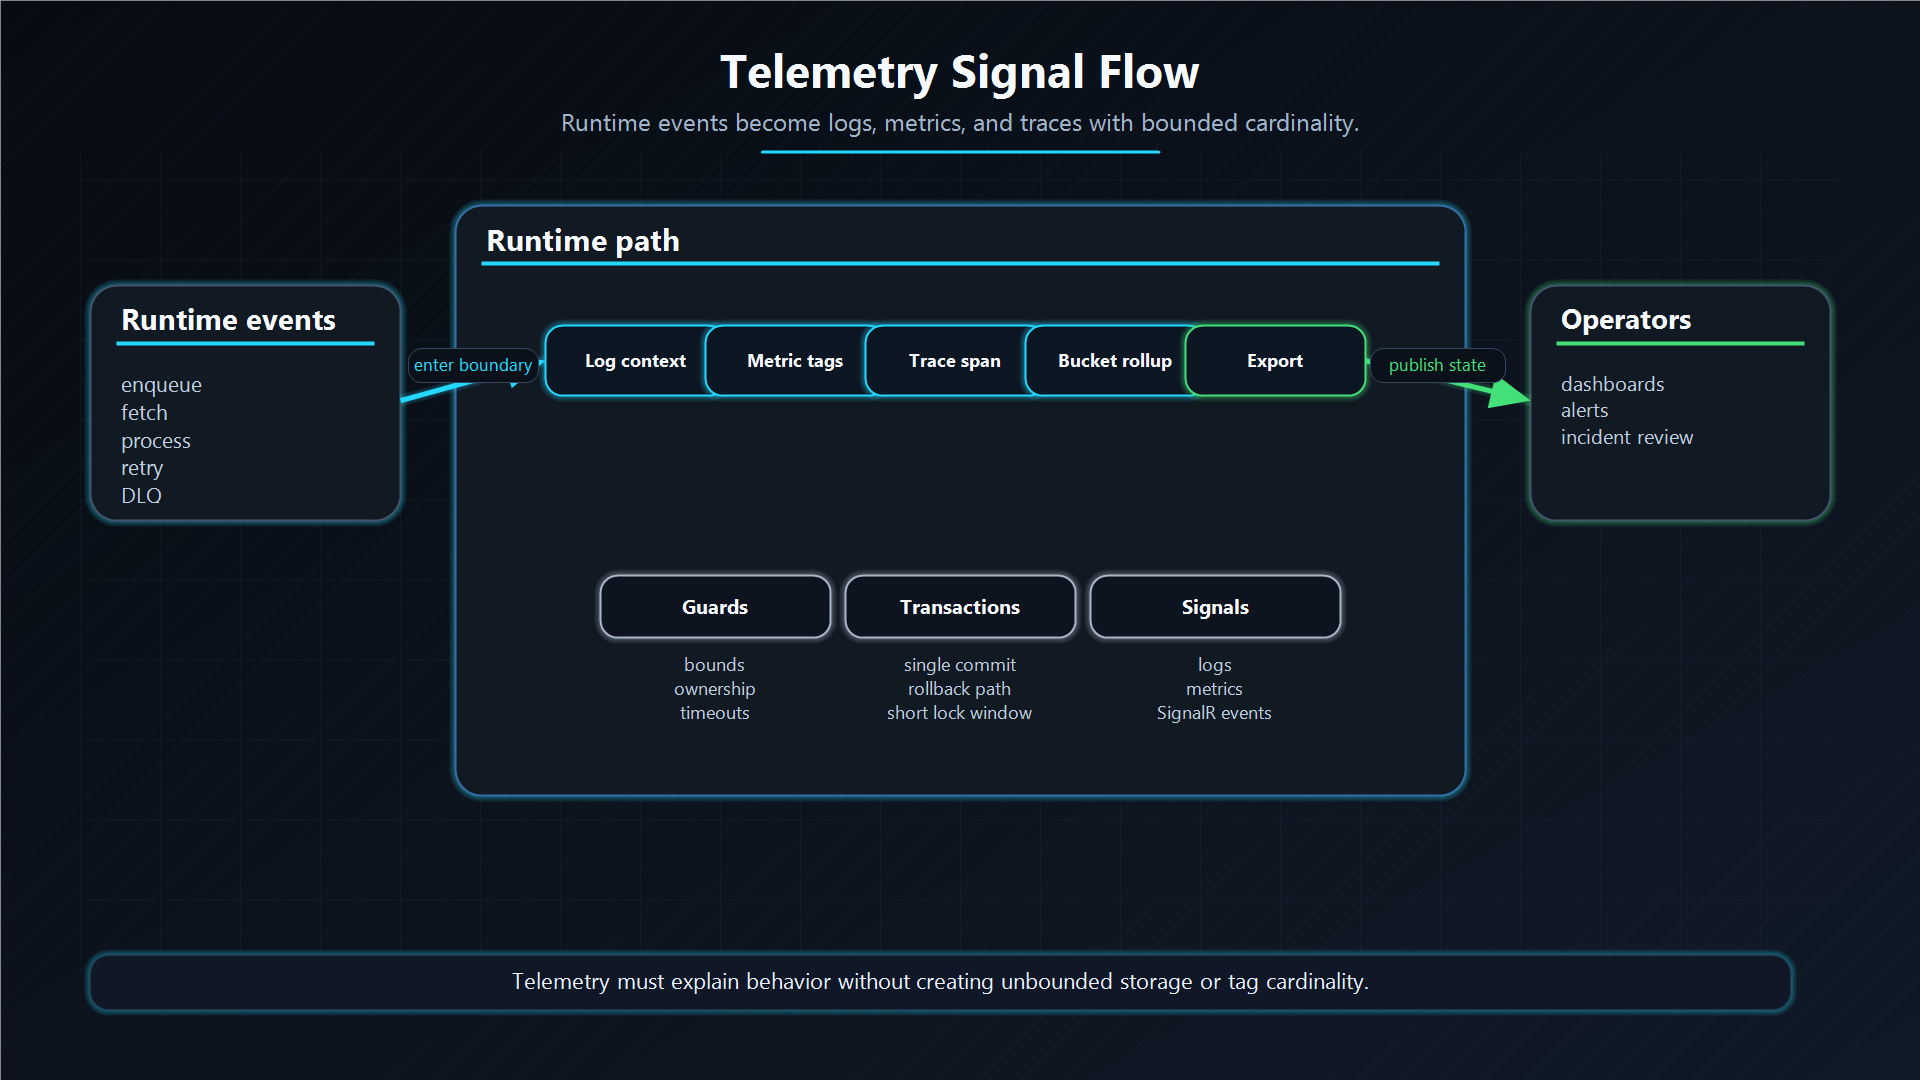
Telemetry is the combined runtime signal surface: metrics, logs, health checks, The Deck notifications, and durable dashboard aggregates.
ChokaQ separates telemetry by purpose. Metrics are for trend and alerting. Logs are for event evidence. Health checks are for infrastructure decisions. The Deck is for live operator workflow. SQL state is the source of truth.
Signal Types
| Signal | Purpose |
|---|---|
| OpenTelemetry metrics | Alerting, dashboards, autoscaling, SLOs. |
| Structured logs | Debugging and incident timelines. |
| Health checks | Load balancer and infrastructure health. |
| SignalR notifications | Real-time operator updates in The Deck. |
MetricBuckets | Durable recent throughput/failure aggregates. |
| SQL tables | Authoritative job state. |
Important Events
The runtime logs worker lifecycle, retry scheduling, DLQ moves, heartbeat failures, circuit breaker events, zombie rescue, state-transition conflicts, and prefetched-job release problems.
These events should be searchable by job ID, queue, job type, and worker ID where available.
Health vs Metrics
Health checks answer: "Should infrastructure treat this host as healthy?"
Metrics answer: "What is changing over time?"
A host can be technically healthy while queue lag is growing. That is why production operations should alert on lag and failure-rate metrics, not only HTTP health status.
Architecture Decision
Why this pattern?
No single telemetry surface is enough. Background job systems need both machine-readable signals and operator-readable state.
Trade-offs
More signals mean more documentation and alert design. The payoff is lower incident ambiguity: operators can see whether the problem is queue lag, SQL connectivity, handler failures, heartbeat failures, or circuit protection.
Alternatives considered
| Alternative | Benefit | Cost |
|---|---|---|
| Logs only | Easy to emit. | Hard to alert and aggregate accurately. |
| Metrics only | Good for SLOs. | Weak payload/state investigation. |
| Dashboard only | Operator friendly. | Needs metrics or logs for automated alerting. |
Additional Questions
What is the source of truth?
SQL storage is authoritative for job state. Metrics and SignalR are derived signals.
What is the first saturation signal?
Queue lag, because it measures how long eligible work waits.
Why keep MetricBuckets if OpenTelemetry exists?
The Deck needs fast local rolling windows from durable state without depending on an external metrics backend.